Laya vs LLMs vs BERT
Question Is the newest model the right choice for a real decision task?
Laya, BERT models and LLMs tested side by side on routing consumer complaints and flagging fraud.
2026 · Personal project
- accuracy, small model + LLMthe same LLM alone: 79.2%
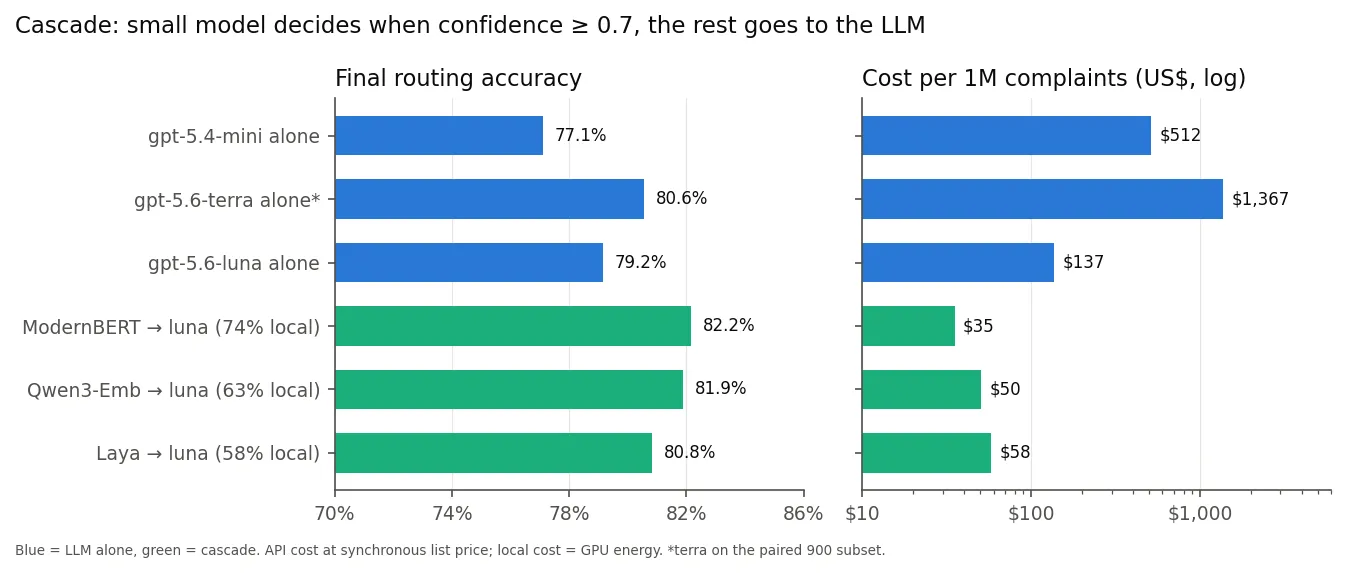
- 82.2%
- per 1M complaintsmost expensive model: US$ 1,367
- US$ 35
- Laya, fine-tuned45% zero-shot; gpt-5.4-mini: 77.1%
- 76.8%
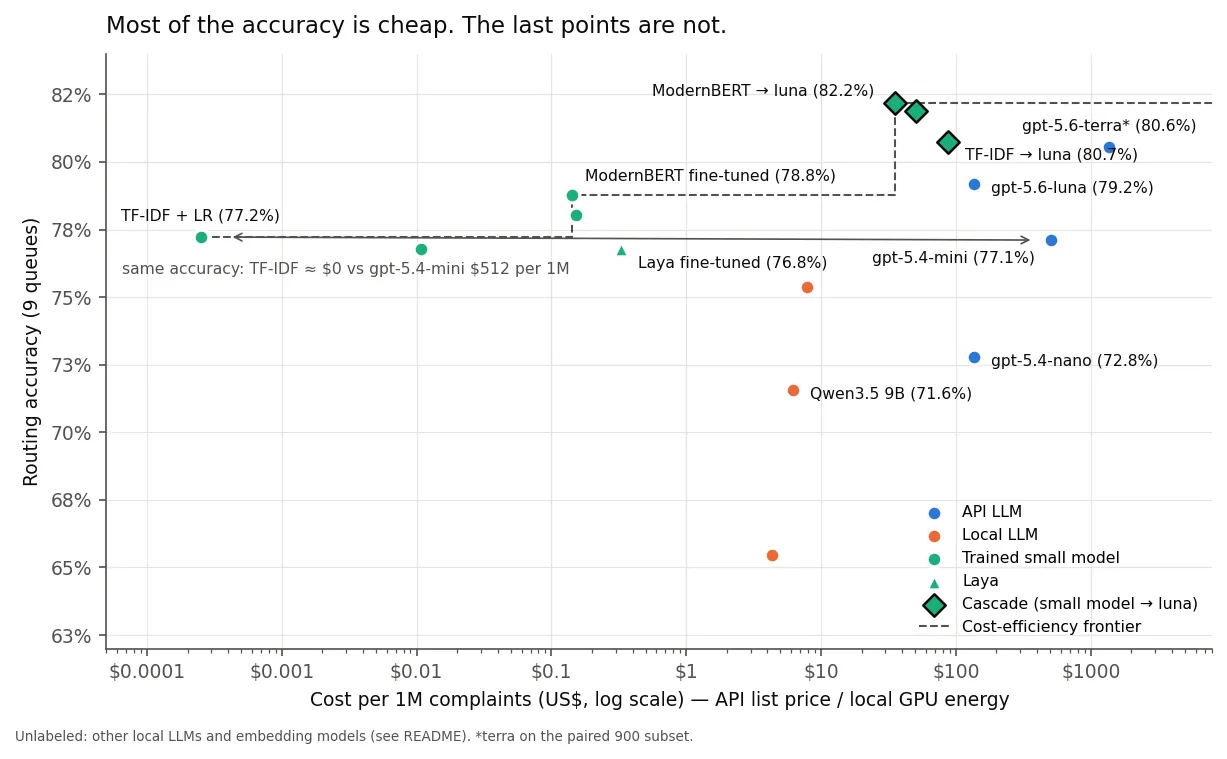
- TF-IDF baselinetied with gpt-5.4-mini (77.2% vs 77.1%)
- 1 ms
Laya is the open-source counterpart of Jev, a “System 1” model that makes typed decisions with calibrated probabilities instead of generating text. Here it faces 12 other systems on the same 1,800 complaints.
Findings
- Out of the box, Laya isn’t ready: 45% accuracy zero-shot, with badly calibrated probabilities.
- Fine-tuned, it matches gpt-5.4-mini (76.8% vs 77.1%), with better calibration and 12x lower latency.
- The newest option wasn’t the best: ModernBERT, Laya’s own backbone, fine-tuned the ordinary way reached 78.8%, and a 20-line TF-IDF + logistic regression tied gpt-5.4-mini in 1 ms.
- LLMs were slow and overconfident: about 1 s per decision; when gpt-5.4-mini said 97% fraud, it was right 62% of the time.
- Combining models gave the best result: ModernBERT answers when confident (74% of complaints) and passes the rest to gpt-5.6-luna.
How it was measured
- 1,800 US consumer-finance complaints (CFPB, public), each routed to one of 9 teams and checked for a fraud report; 3,600 more for training.
- 13 systems: classic ML, fine-tuned small models, local LLMs (Ollama) and GPT models via API. Versions and prices as of September and October 2026.
- Accuracy, calibration, latency and cost per 1M complaints. Every system answered the same complaints, so comparisons are paired and tested for significance.
- Local runs on one RTX 3060; the API calls for the whole experiment cost about US$ 2.20.
Limitations
- Labels are what consumers picked in a form, so the ceiling is below 100%.
- The test set is balanced by team and enriched for fraud (21.2%), unlike production.
- English only, one split and one seed per model, the same prompt for every LLM.
- Jev itself was not tested (early access only).
More charts
Stack
- Python
- Hugging Face Transformers
- OpenAI API
- scikit-learn
- ModernBERT
- Laya
- Ollama